Developer Resources
Jev Model Typesafe: A Practical Guide to Typed AI Decisions
Understand the Jev Model and its TypeSafe connection, then learn how typed questions, probabilities, and the Jev API fit into production software workflows.
Jev Model Typesafe: A Practical Guide to Typed AI Decisions
The search phrase “Jev Model typesafe” usually points to a simple but important question: what is the relationship between the Jev Model, the typesafe/jev-1.13 model identifier that appears in the Playground, and the software company or model family associated with TypeSafe?
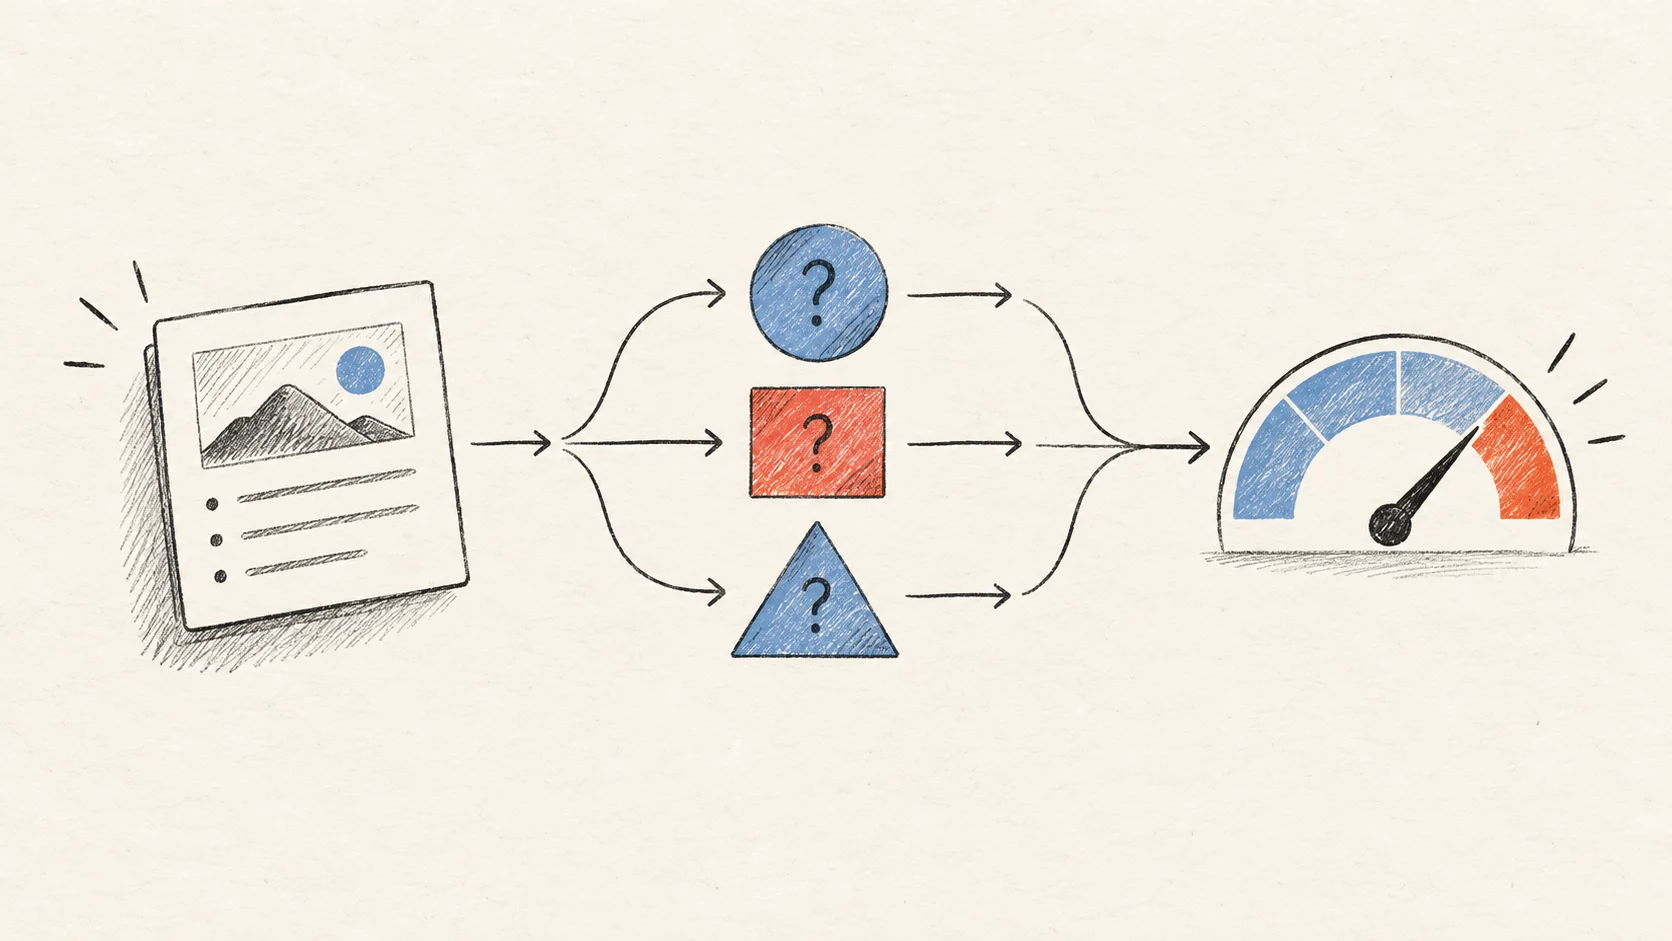
The useful answer is not just a name. Jev is designed around a different unit of work from a conventional chat model. Instead of asking a model to write a paragraph and then asking application code to infer what that paragraph means, you provide a state and a set of bounded questions. Jev returns typed decisions, probabilities, and—where relevant—confidence signals that your code can route, score, queue, or review.
This article explains the model in practical terms, shows the request shape, and separates the parts that Jev can handle from the parts your application must still own. If you are looking for the product overview first, read the Jev Model overview; this guide focuses on implementation choices and the TypeSafe naming question.
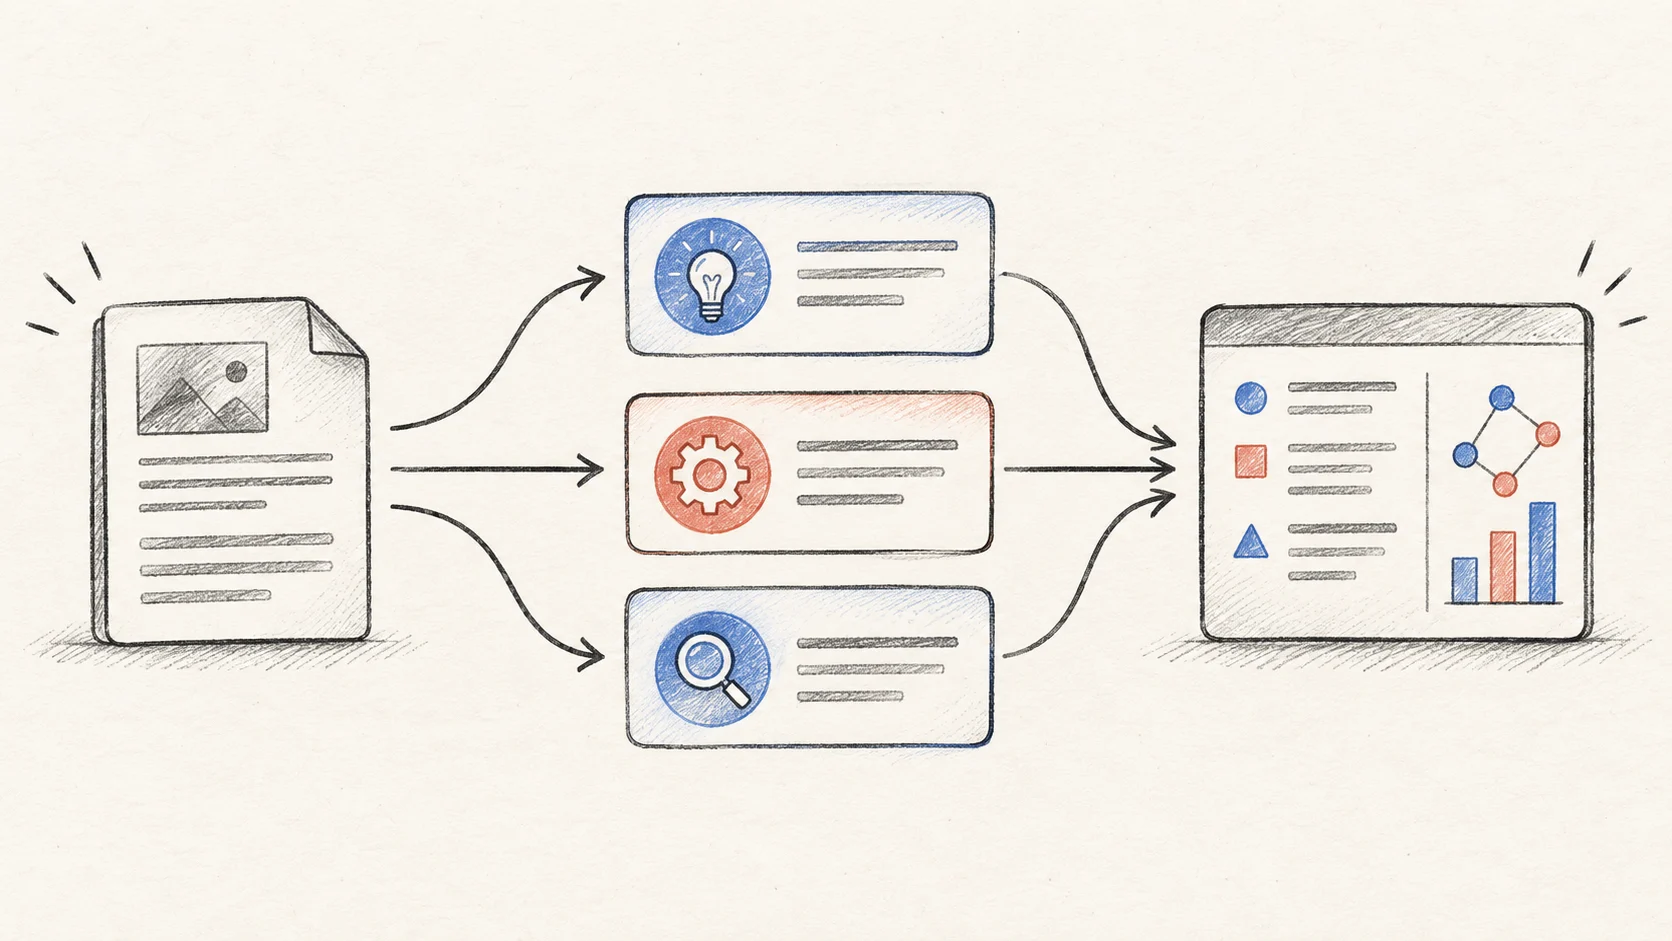
Table of contents
- The short answer
- What the Jev Model is built to do
- Why typed decisions are different from generated text
- State and questions: the core interface
- Choice, Score, and Noul
- From the Playground to the Jev API
- What “TypeSafe” means in the workflow
- Production boundaries and evaluation
- Who should use Jev Model
- Frequently asked questions
The short answer
Jev is a decision-oriented AI model available through jevmodel.net. Its public interface is built around three pieces:
- State — the text, JSON object, or array of text that contains the context.
- Typed questions — a map of specific questions, each using a defined answer type.
- Structured answers — the result for each question, including a selected option, score, yes-probability, and supporting probability fields where the type provides them.
The Playground currently exposes a model value such as typesafe/jev-1.13, while the API documentation uses jev-latest as the flagship model name. Treat those as model identifiers, not as a promise that Jev is a general-purpose text generator. The stable idea is the interface: send context, define the answer space, and let application code make the next move.
That distinction is especially useful for classification, routing, moderation, triage, risk checks, lead scoring, and agent guardrails. It is less useful when the primary output is an essay, a conversation, source code, or another piece of open-ended text.
What the Jev Model is built to do
Most language-model APIs are optimized for token generation. You send instructions and context, then receive a sequence of tokens. Even when the response is formatted as JSON, the application often has to validate whether the shape is correct, whether an option is allowed, and whether a free-form explanation actually implies a safe action.
Jev starts from a narrower software question: which bounded decision should the program consume? The answer space is described before inference. That gives the developer a more explicit contract:
| Layer | Responsibility |
|---|---|
| Your application | Authenticate users, assemble state, define policy, validate input, and execute actions |
| Jev | Evaluate the state against the questions and return typed decision signals |
| Your application | Apply thresholds, permissions, fallbacks, logging, and human review |
This division does not eliminate model uncertainty. It makes the uncertainty easier to expose and handle. A Choice answer can include probabilities for each allowed option. A Score answer can include a weighted score and a probability distribution across levels. A Noul answer gives a value between 0 and 1 representing the probability that a focused proposition is true.
The model therefore fits in the middle of an existing system. It does not need to own the entire workflow. You can place it after a parser, before a queue, beside a generative model, or inside an agent loop that needs a separate approval signal.
Why typed decisions are different from generated text
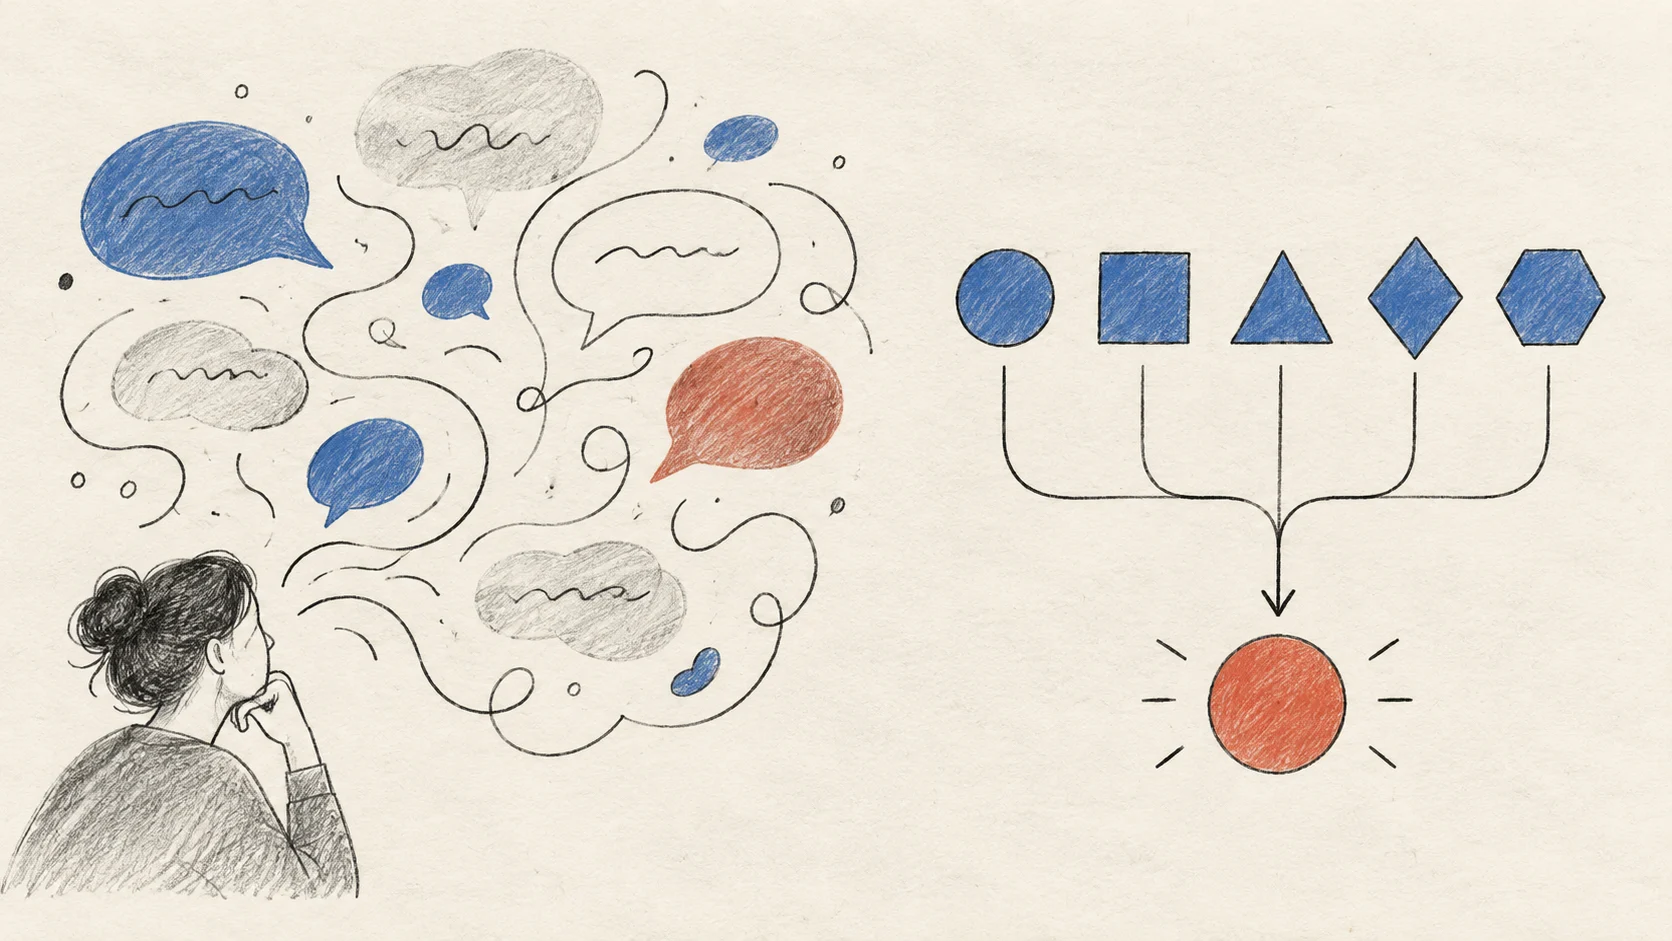
Consider a support ticket that says, “The customer has been waiting three days and is asking for a refund.” A generative model might produce a helpful summary. That summary is useful for a human, but the queue still needs machine-readable values:
- Which team owns the ticket?
- How urgent is it?
- Does the request match the refund policy?
- Should it be escalated to a person?
With a free-form model, you can ask for JSON, but you still need to guard against a new label, a malformed number, a missing field, or a confident-sounding explanation that contradicts the policy. With Jev, you describe the options and the rubric first. The returned fields map to those questions, so your downstream code can stay small and explicit.
This is not an argument that Jev replaces a large language model. The two systems solve different shapes of problem. A generative model can draft the customer reply; Jev can judge the queue, urgency, and review path; deterministic policy code can decide whether a refund is permitted.
The boundary is clearest when the consequence of a wrong decision is known. Routing an email to a queue is one kind of risk. Deleting an account or approving a payment is another. In the second case, a probability from any model should be treated as a signal—not as authorization.
State and questions: the core interface
State is the context shared by every question in one evaluation. Use a string for a simple message, an object when fields have distinct meaning, or an array of text when several pieces of context should be evaluated together. The current public documentation describes text, JSON objects, and arrays of text as supported input boundaries; it does not position Jev as an image, audio, or video model.
A focused object is usually the best starting point for application code:
{
  "model": "jev-latest",
  "state": {
    "ticket_text": "The customer has waited three days for a refund.",
    "account_tier": "pro",
    "refund_window_days": 30,
    "days_waiting": 3,
    "policy": "Refund requests inside the window may be reviewed automatically."
  },
  "questions": {
    "queue": {
      "type": "choice",
      "instructions": "Which team should handle this ticket?",
      "criteria": {
        "billing": "Payment, refund, invoice, or charge issue",
        "support": "Product usage or account help",
        "trust": "Abuse, fraud, or policy concern"
      }
    },
    "urgency": {
      "type": "score",
      "instructions": "How urgent is this ticket?",
      "criteria": ["routine", "soon", "high", "critical"]
    },
    "needs_human": {
      "type": "noul",
      "instructions": "Does this case require human review before an action is taken?"
    }
  }
}
Each question should be atomic. “What should we do with this ticket?” is too broad to audit. “Which queue applies?” and “Does this need review?” are easier to test, compare, and connect to code. Multiple questions can share one state and be evaluated in parallel, which is often cleaner than making separate model calls for every signal.
The question key—queue, urgency, or needs_human in the example—is chosen by your application and reused in the response. Keep keys stable. Stable keys make it possible to compare model versions, track threshold changes, and build dashboards without rewriting the event schema.
Choice, Score, and Noul
Choice: select from an allowed set
Use Choice when the next step is one of a defined set: route to a team, select a model, classify an intent, or choose an approved workflow. The criteria map gives every option a meaning. Your code can then switch on the returned choice without interpreting a paragraph.
Do not create options that overlap heavily. “Technical,” “product,” and “other technical” will create ambiguity. Prefer labels that correspond to concrete owners or actions, and keep a fallback path in application code even if the model returns an allowed value.
Score: rate against an ordered rubric
Use Score when the answer belongs on a meaningful low-to-high scale: severity, urgency, satisfaction, or review priority. The criteria array gives the levels an order, while the response can include a probability-weighted score and a legend.
The scale should be operational, not decorative. If level three means “page the on-call engineer,” define it that way. A numeric score without a decision attached is merely a metric; a score tied to a queue or threshold becomes part of a workflow.
Noul: estimate whether a proposition is true
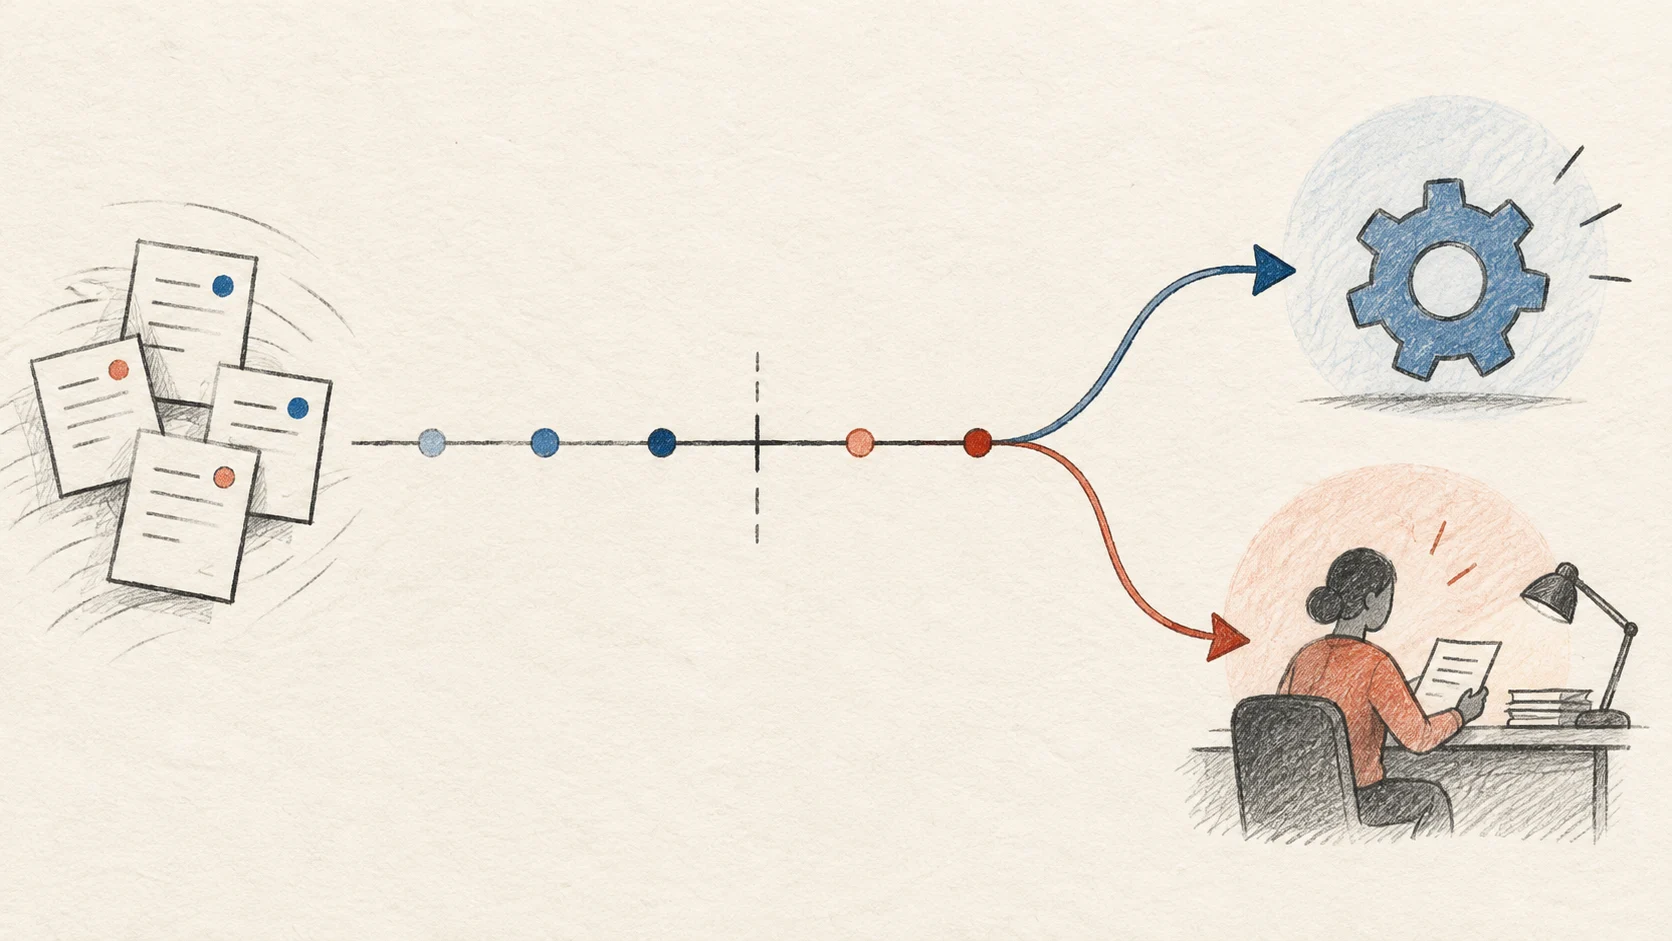
Use Noul for a focused yes/no judgment: “Is the message urgent?” “Does this action require approval?” or “Is the evidence sufficient to continue?” Its result is a 0-to-1 value representing the probability of yes.
Noul is useful because a binary business rule often needs a confidence boundary. An internal notification might continue at 0.65. A destructive action might require 0.95 plus a separate policy check—or might never be automated at all. The right threshold depends on the cost of false positives and false negatives, not on a universal number.
From the Playground to the Jev API
The fastest way to learn the interface is to test a real case in the Jev Playground. Put representative state into the input, define one or two narrow questions, and inspect the complete response rather than only the winning label.
When the question is useful, move it to a server-side integration. The public API reference documents the evaluation endpoint as:
POST https://jevmodel.net/v1/systemone
Send an API key with the Authorization: Bearer header and use application/json. A minimal request from a server might look like this:
curl -X POST https://jevmodel.net/v1/systemone \
  -H "Authorization: Bearer $JEV_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-latest",
    "state": "Three deploys failed and production returns HTTP 500.",
    "questions": {
      "needs_human": {
        "type": "noul",
        "instructions": "Does this incident need a person to investigate now?"
      }
    }
  }'
The API key belongs in a server-side environment variable. Do not place it in browser JavaScript, a public repository, client-side logs, or an agent prompt that may be recorded. For request fields, response shapes, errors, and the current naming of the flagship model, use the Jev API documentation as the source of truth.
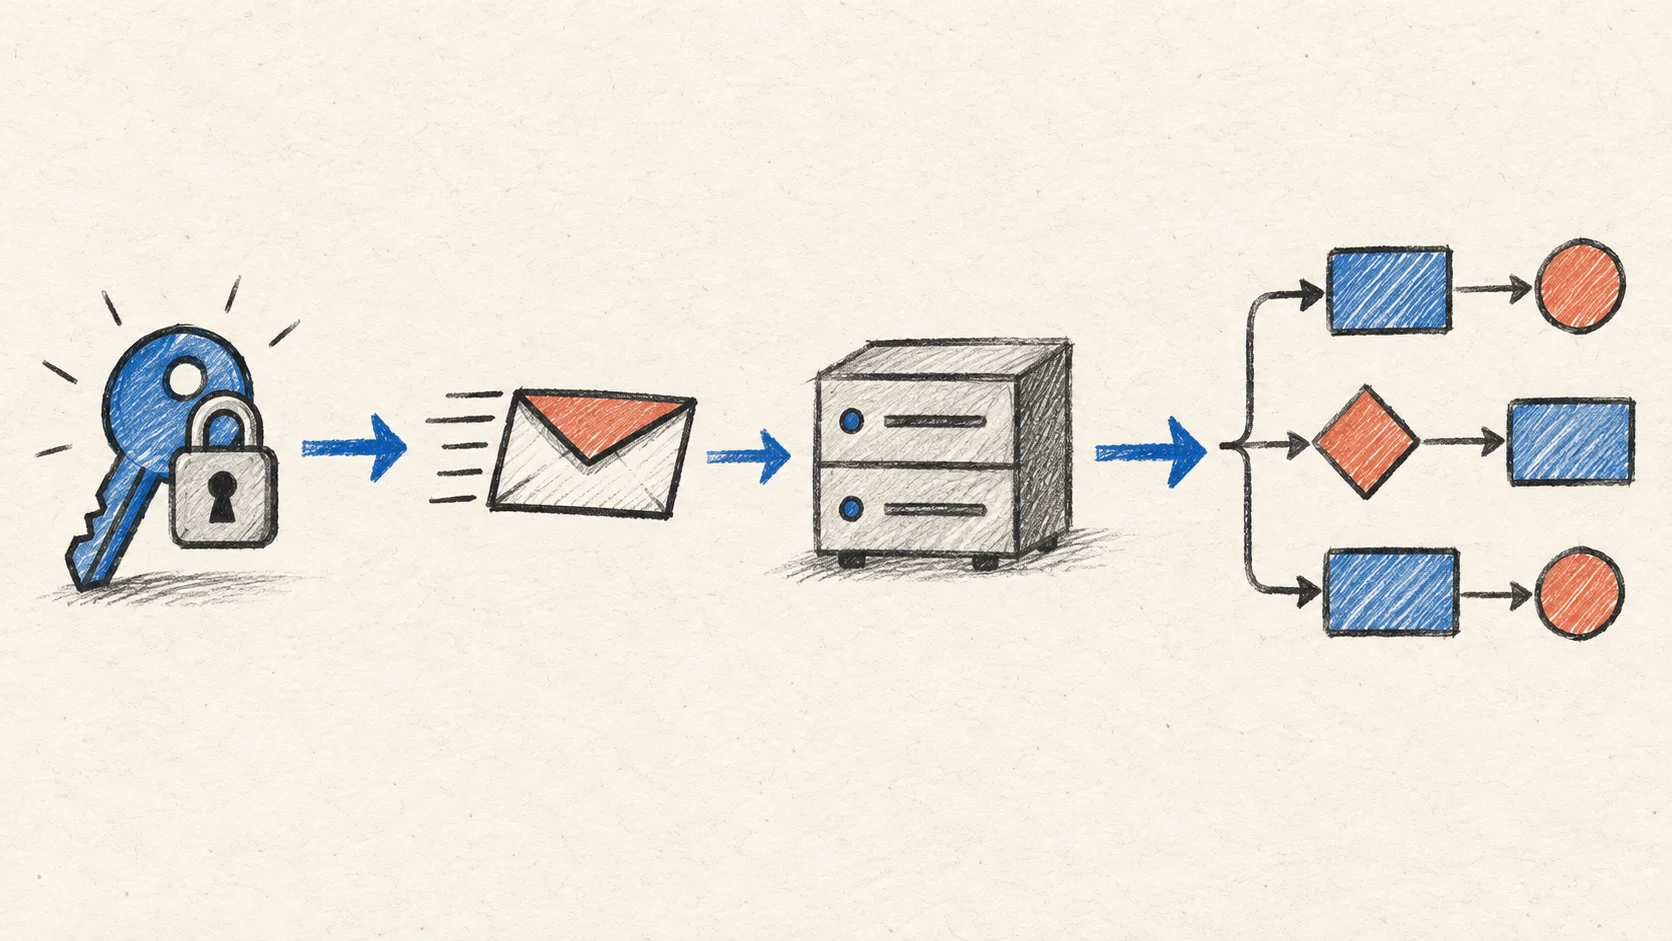
Your integration should treat the response as an input to a decision function, not as an instruction to bypass the rest of the system:
const answer = result.answers.needs_human;

if (answer.type !== 'noul') {
  return failClosed('Unexpected answer type');
}

if (answer.noul >= 0.8) {
  return queueForReview({ incidentId, signal: answer.noul });
}

return continueWithDeterministicChecks({ incidentId });
In production, add timeouts, retries with a cap, request IDs, schema validation, error handling, and a safe behavior for an unavailable model. A system that cannot get a judgment should not silently convert “unknown” into “approved.”
What “TypeSafe” means in the workflow
The keyword “TypeSafe” can be confusing because it may refer to a product or company name, a model namespace, or simply the promise of structured software-facing output. The practical way to read the current Jev experience is to inspect the exact surface you are using:
- The Playground can show an identifier such as
typesafe/jev-1.13. - The API documentation currently presents
jev-latestas the flagship model name. - The product interface is available through jevmodel.net, including the Playground, API docs, keys, and pricing.
- The website footer includes an independence notice, so do not infer a corporate relationship from a namespace alone. Verify current ownership, licensing, and commercial terms from the official pages before publishing a legal or procurement claim.
In other words, “TypeSafe” is useful search context, but the developer contract is the typed-decision interface. A safe implementation should pin or monitor the model identifier you use, keep request and response examples under version control, and rerun an evaluation set after a model or rubric change.
Production boundaries and evaluation
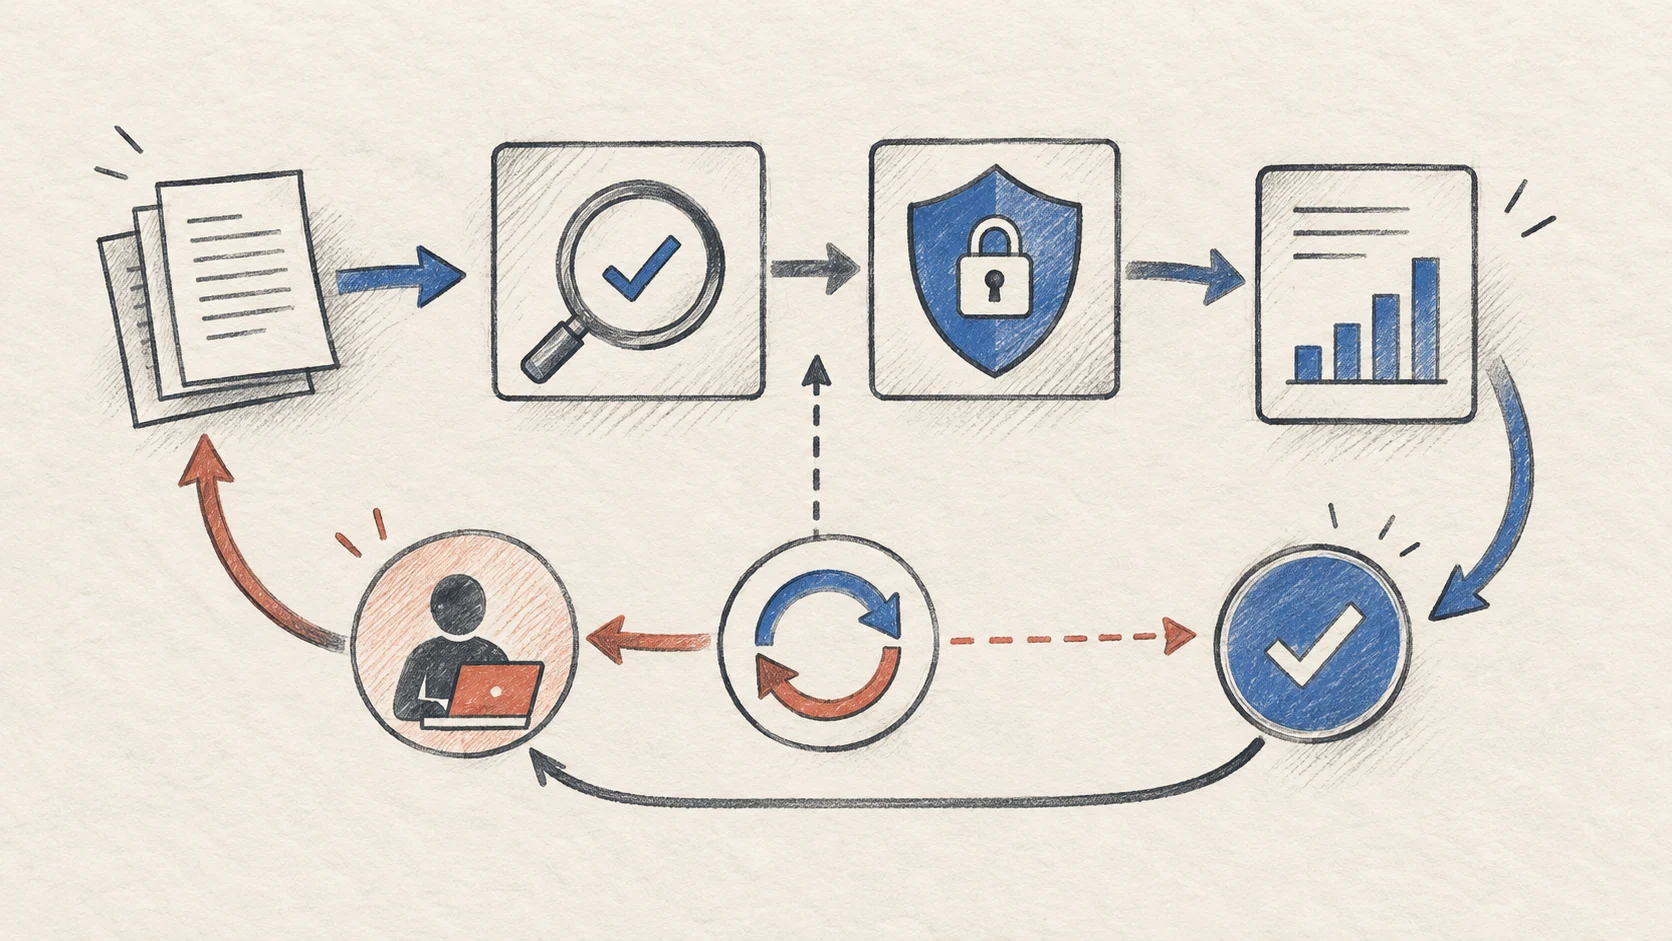
The strongest Jev integration is usually small. Start with one decision where you have historical examples and a clear action after each outcome. Build a labeled evaluation set before tuning thresholds. Include ordinary cases, edge cases, missing fields, adversarial wording, multilingual inputs if relevant, and examples where humans disagree.
Track at least four things:
- Decision quality — compare the selected option or score with a trusted human label.
- Calibration — check whether a probability of 0.8 actually behaves like an 80% rate in the slice you care about.
- Operational outcome — measure queue time, review volume, false escalations, or prevented incidents.
- Fallback behavior — confirm that timeouts, unsupported inputs, and invalid responses fail safely.
Use different thresholds for different risks. A low-impact content tag may tolerate automatic routing at a lower confidence. A payment, deletion, account lock, or security action should involve deterministic policy checks and usually a human approval path. Model confidence is not the same as business accuracy, and neither one is the same as authorization.
Keep the state minimal and intentional. Remove secrets, unnecessary personal data, and irrelevant history. Include the policy or rubric that the question needs, but do not send the entire application database when a handful of fields will answer the decision.
Finally, log enough information to reproduce a decision: model identifier, question version, state schema version, answer, probabilities, threshold, final application action, and whether a human overrode it. Redact API keys and sensitive payloads, and define a retention period before shipping.
Who should use Jev Model
Jev is a good candidate when all of the following are true:
- the decision has a bounded answer space;
- the same judgment happens repeatedly at useful volume;
- the result should be consumed by code;
- you can describe what each option or score level means;
- you can measure outcomes or review a sample of decisions.
Typical starting points include support triage, lead qualification, content moderation signals, model routing, tool-call guardrails, document classification, and “does this need review?” checks inside an agent workflow.
Use a generative model instead—or combine one with Jev—when you need drafting, summarization, dialogue, explanation, code generation, or broad exploration. Jev can judge a draft or route a task, but it is not a replacement for every model in a product.
For the difference in responsibilities between Jev and a traditional LLM, start with the Jev Model homepage, then confirm current access options on the Jev pricing page. The API docs linked above remain the source of truth for request and response details.
Frequently asked questions
Is Jev Model the same as a normal LLM?
No. A normal LLM is generally used to generate text token by token. Jev is presented as a decision-oriented model: you define typed questions and receive structured answers that application code can use.
What does typesafe/jev-1.13 mean?
It is a model identifier shown in the current Playground experience. The API documentation uses jev-latest for the flagship API model. Confirm the identifier and behavior in the surface you are integrating, and keep your integration ready for model-version changes.
Can Jev return a probability?
Yes. Choice can return probabilities for its options, Score can return per-level probabilities and a weighted score, and Noul returns a yes-probability from 0 to 1. Treat these values as decision signals, not guarantees.
Can I use images or audio as Jev state?
The current public API documentation describes text, JSON objects, and arrays of text. It does not currently list image, audio, or video input for the hosted Jev API. If your decision depends on media, use a suitable multimodal system upstream and send the relevant extracted state into the decision step.
Does Jev replace application permissions?
No. The application must still authenticate the user, check permissions, validate tool names and parameters, enforce policy, and decide whether to execute. A model answer should never be the only authorization layer.
What is the best first Jev use case?
Choose one low-risk, high-volume decision with a clear label and a measurable outcome. Validate it in the Playground, move the smallest useful request to the API, then add thresholds, logging, and a human-review fallback before expanding the scope.